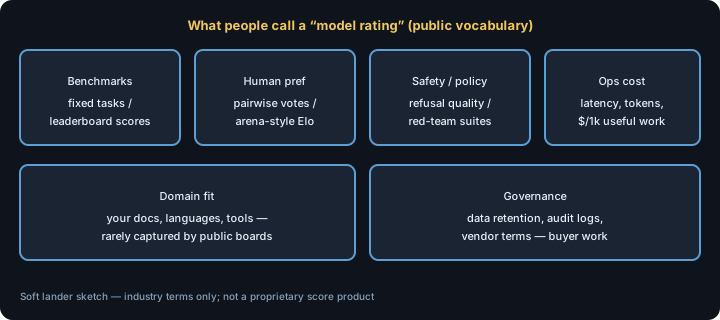
ModelRaters is a soft front door for a noisy phrase. People say “model rating” when they mean benchmark scores, arena-style preference votes, safety suite results, price-per-useful-token, or whether a model simply survives their prompts. Those are different instruments. Mixing them into one magic number is how buyers get surprised.
Why a soft lander
Vendor decks collapse evaluation into a single rank. Researchers publish task suites with known saturation and contamination risks. Independent arenas track human preference under shifting prompts. Procurement teams still need retention terms, latency budgets, and a pilot that uses real documents. This face stays in that public literacy lane: name the dimensions, slow the overclaim, leave a path for careful updates later.
What you will not find
- Architecture diagrams of private systems.
- Guaranteed ROI or “best model forever” tables.
- Instructions for bypassing safety or usage policies.
What you will find: dense, visual notes on evaluation habits that already show up in public papers, vendor model cards, and buyer playbooks. Start with the essays linked from this face.

Orientation sources (public): published LLM benchmark and arena methodology pages; vendor model cards and pricing docs; NIST AI RMF framing on measurement and risk; academic write-ups on benchmark saturation and contamination. Soft lander — educational framing only.